⭐
⭐
profile photo

Chenxin Li | 李宸鑫

Hi! I'm a Research Scientist at Tencent Hunyuan under the Qingyun Talent Program. I received my Ph.D. from The Chinese University of Hong Kong (CUHK).

I build agentic systems for visual coding, computer use, phone use, robot use, etc., working toward general-purpose multimodal agency.

Previously, I worked as a research intern at ByteDance Seed, Meta MSL, etc. Beyond research, I share perspectives on my blog. Feel free to reach out via email (chenxinli@link.cuhk.edu.hk) or wechat (jasonchenxinli).

Email | LinkedIn | Google Scholar Scholar | GitHub | X | Blogs | 小红书
Selected Works

Visual and Spatial Intelligence through Coding Agents

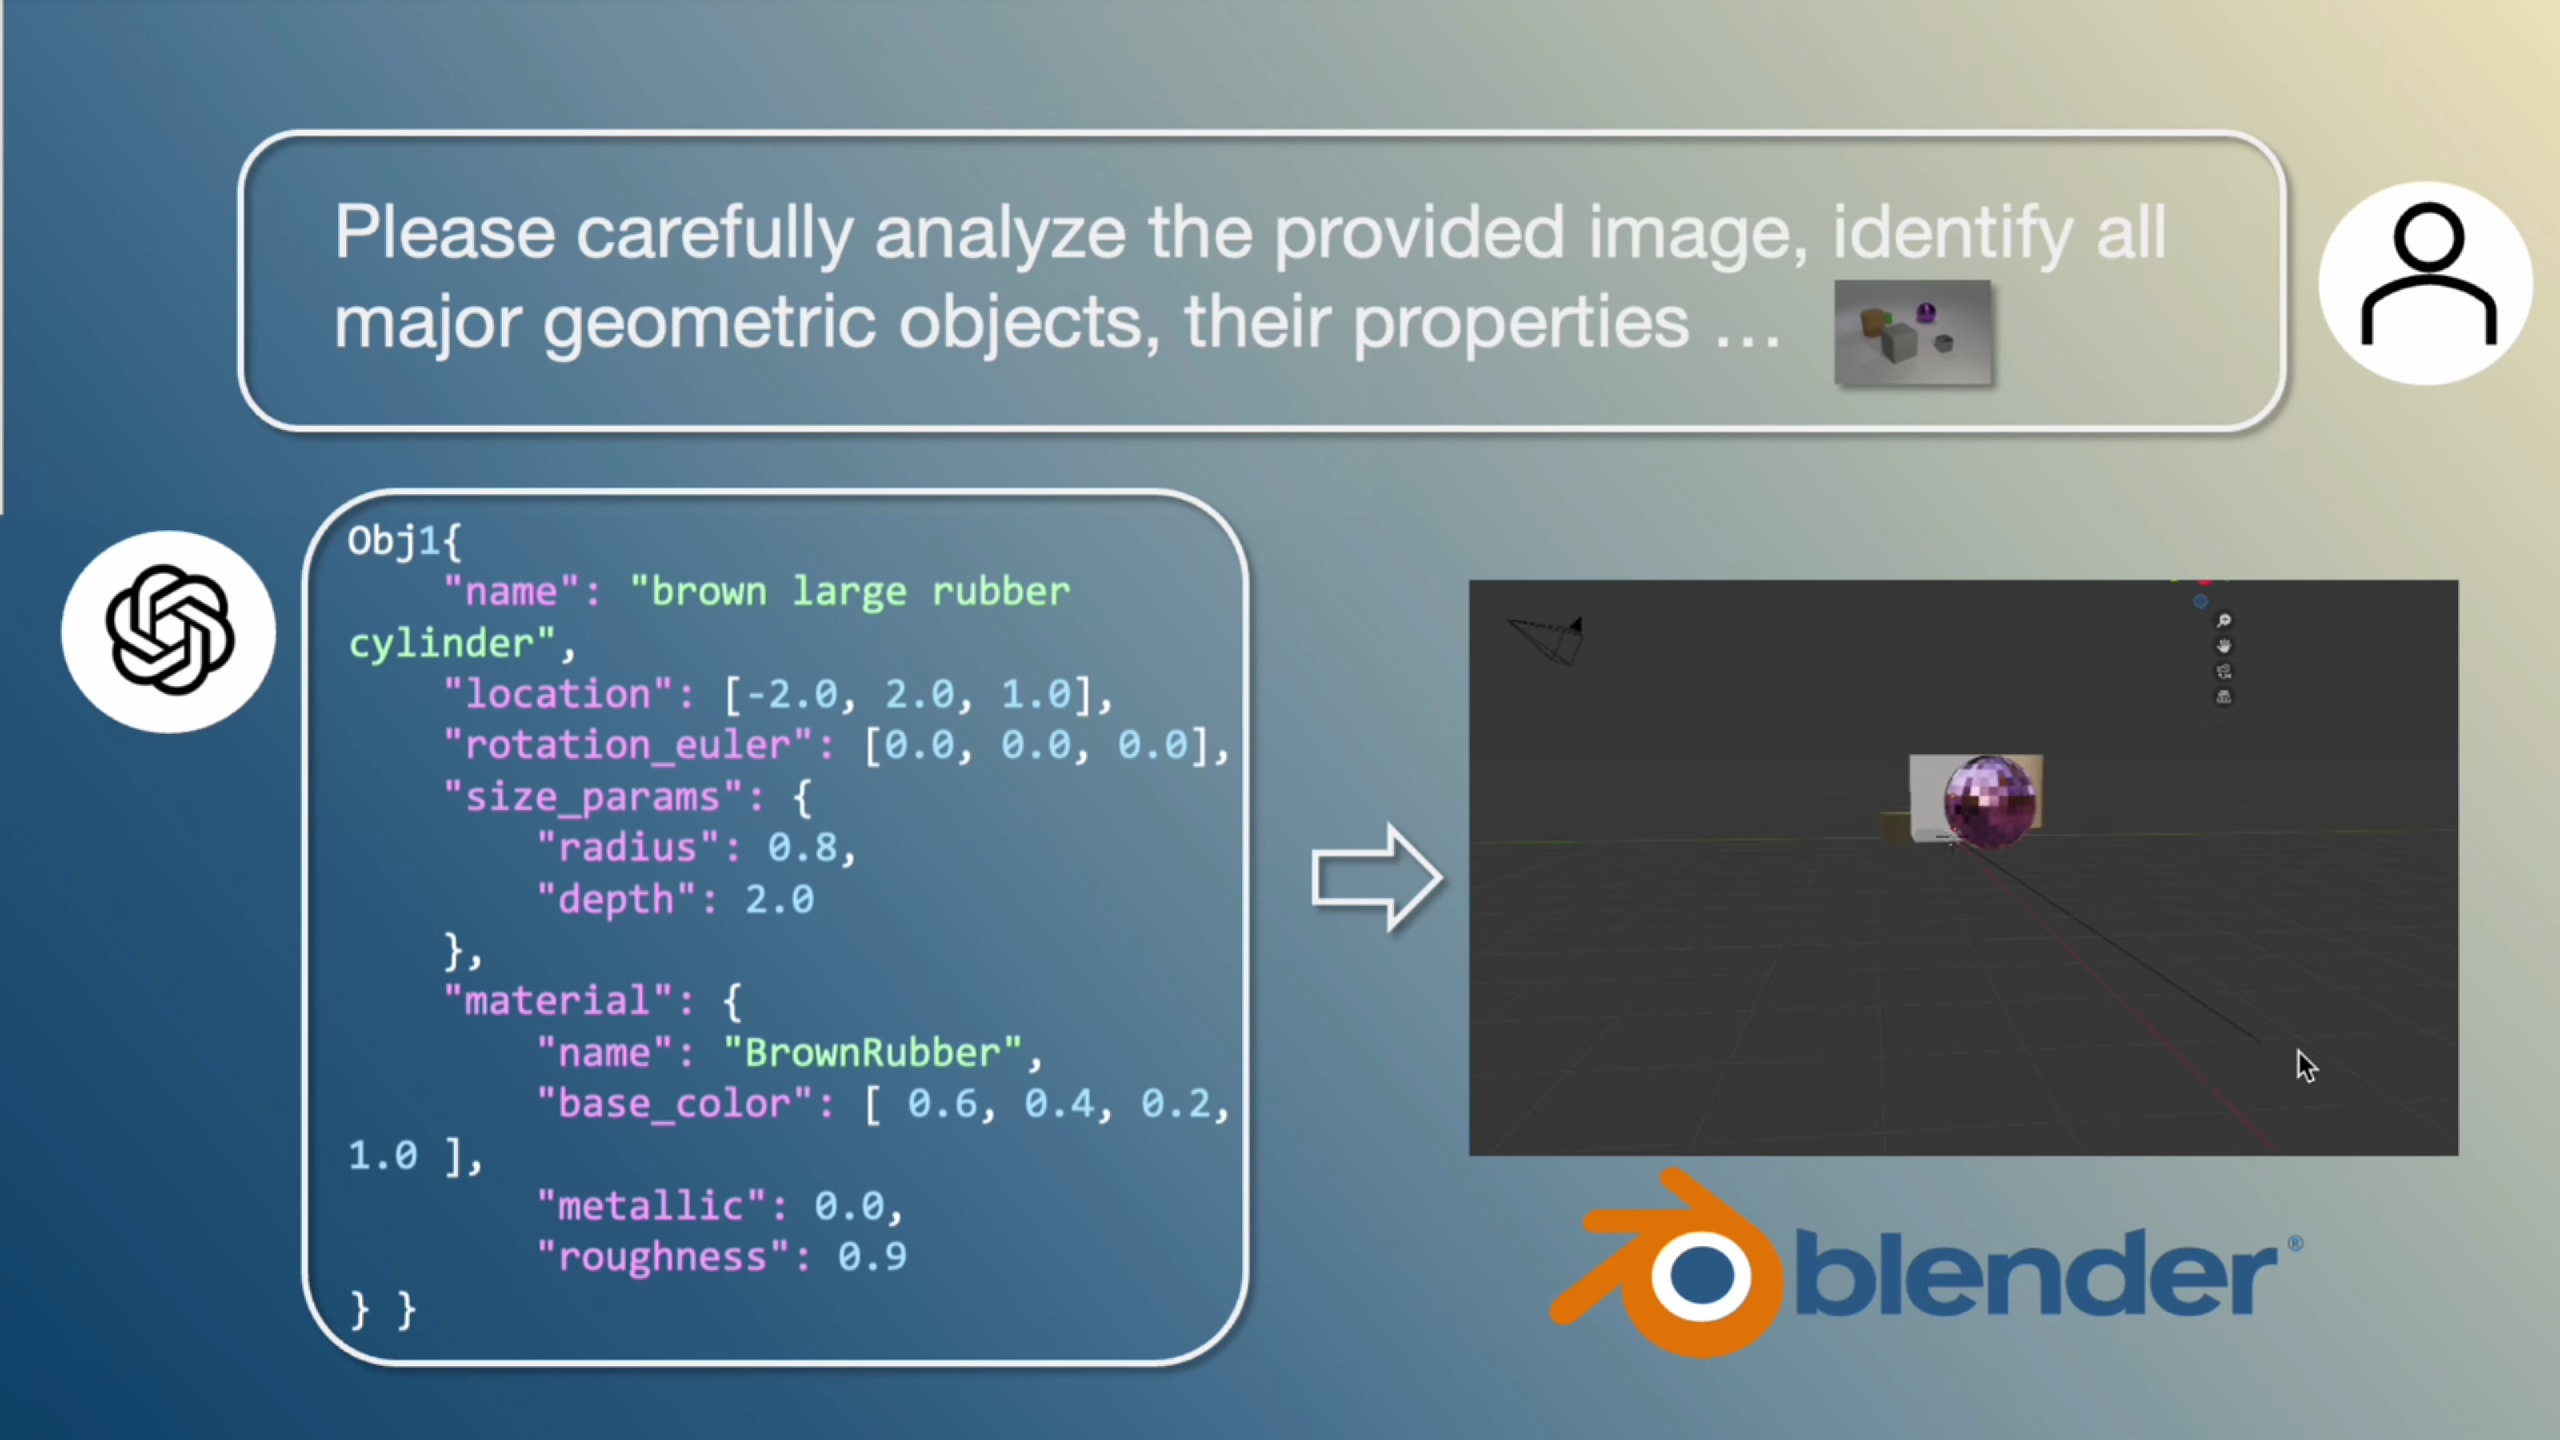
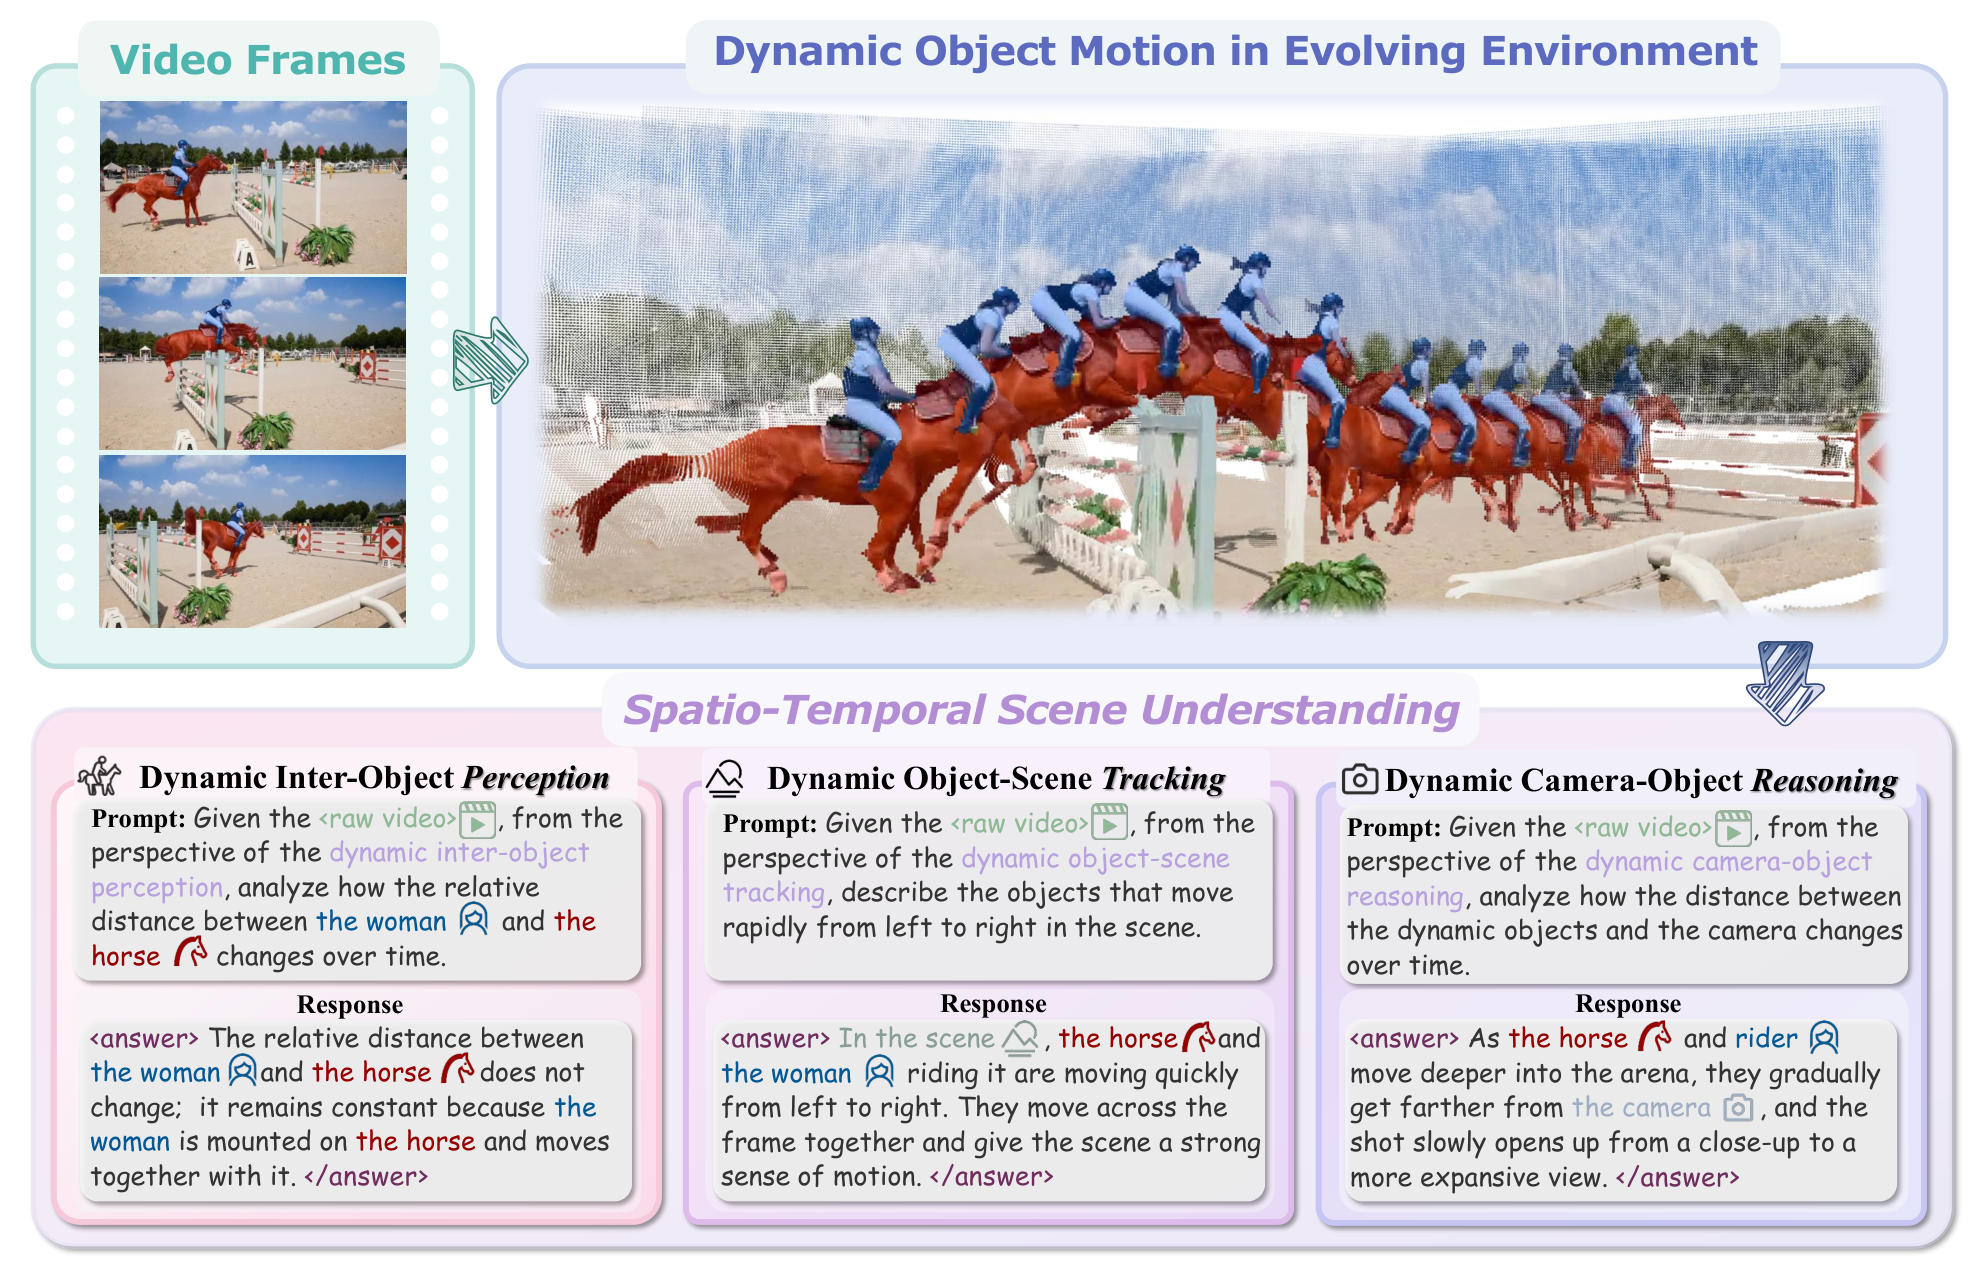
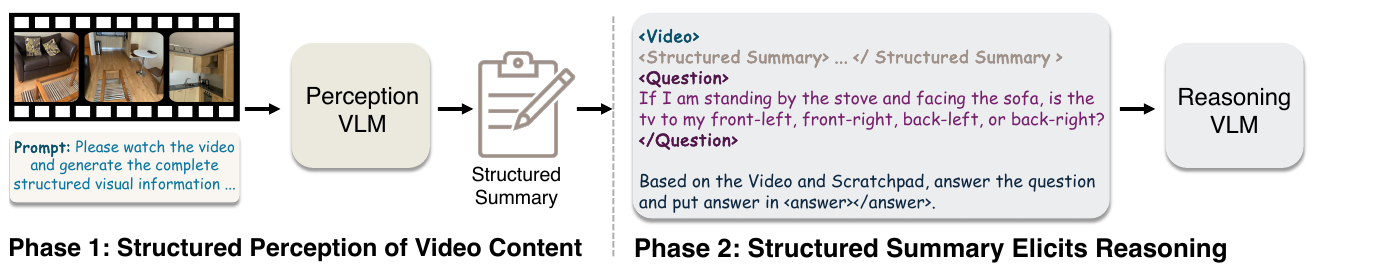
IR3D-Bench and Struct-to-Reason explore visual understanding through executable code and structured representations. RobotWorld and Thinking in Dynamics evaluate multimodal agents’ capabilities in physical reasoning and robot use.

Agent Foundation Models for Coding and Tool Use

Seed2.0 and Seed1.8 combine multimodal understanding, coding, and tool use for complex real-world workflows. UI-TARS-2 focuses on GUI-centered interaction, augmented with terminal and MCP tools.

Recursive Self-improvement (RSI) for Agent Evaluation and Data Synthesis

Claw-Eval (Live) and On-policy Data Evolution study real-world workflow evaluation and agent data self-improvement: verifiable live tasks in Claw-Eval, and rollout-driven training-data evolution in On-policy Data Evolution.

Phone-use Agents: Training, Environments, and Safety

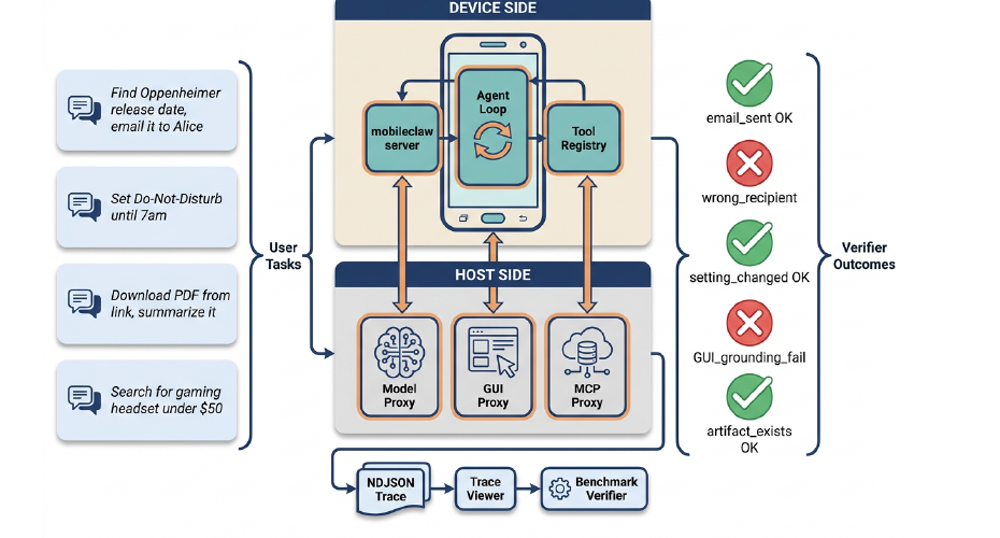
PhoneBuddy, HyMobileAgent, PhoneWorld, and PhoneHarness advance phone-use agents through open-model training, data-environment co-scaling, scalable interactive environments, and mixed CLI/GUI/MCP execution. PhoneSafety and PhonePrivacy complement this line with capability-aware safety and privacy evaluation.

Selected Publications [Google Scholar]
* Equal contribution, † Project Leader, ‡ Corresponding author
RobotWorld: Benchmarking Multimodal Agents for Robot Use Across Diverse Tasks and Embodiments
Zhiqin Yang*, Chenxin Li*†, Xiaomeng Hu*†, Yibin Liu, Weidong Huang, Jiankai Sun, etc.
arXiv preprint, 2026
Seed2.0: Towards Intelligence Frontier for Real-World Complexity
ByteDance Seed Team (including Chenxin Li)
Technical report, 2026
Seed-1.8: Towards Generalized Real-World Agency
ByteDance Seed Team (including Chenxin Li)
Technical report, 2025
UI-TARS-2: Advancing GUI Agent with Multi-Turn Reinforcement Learning
ByteDance Seed Team (including Chenxin Li)
Technical report, 2025
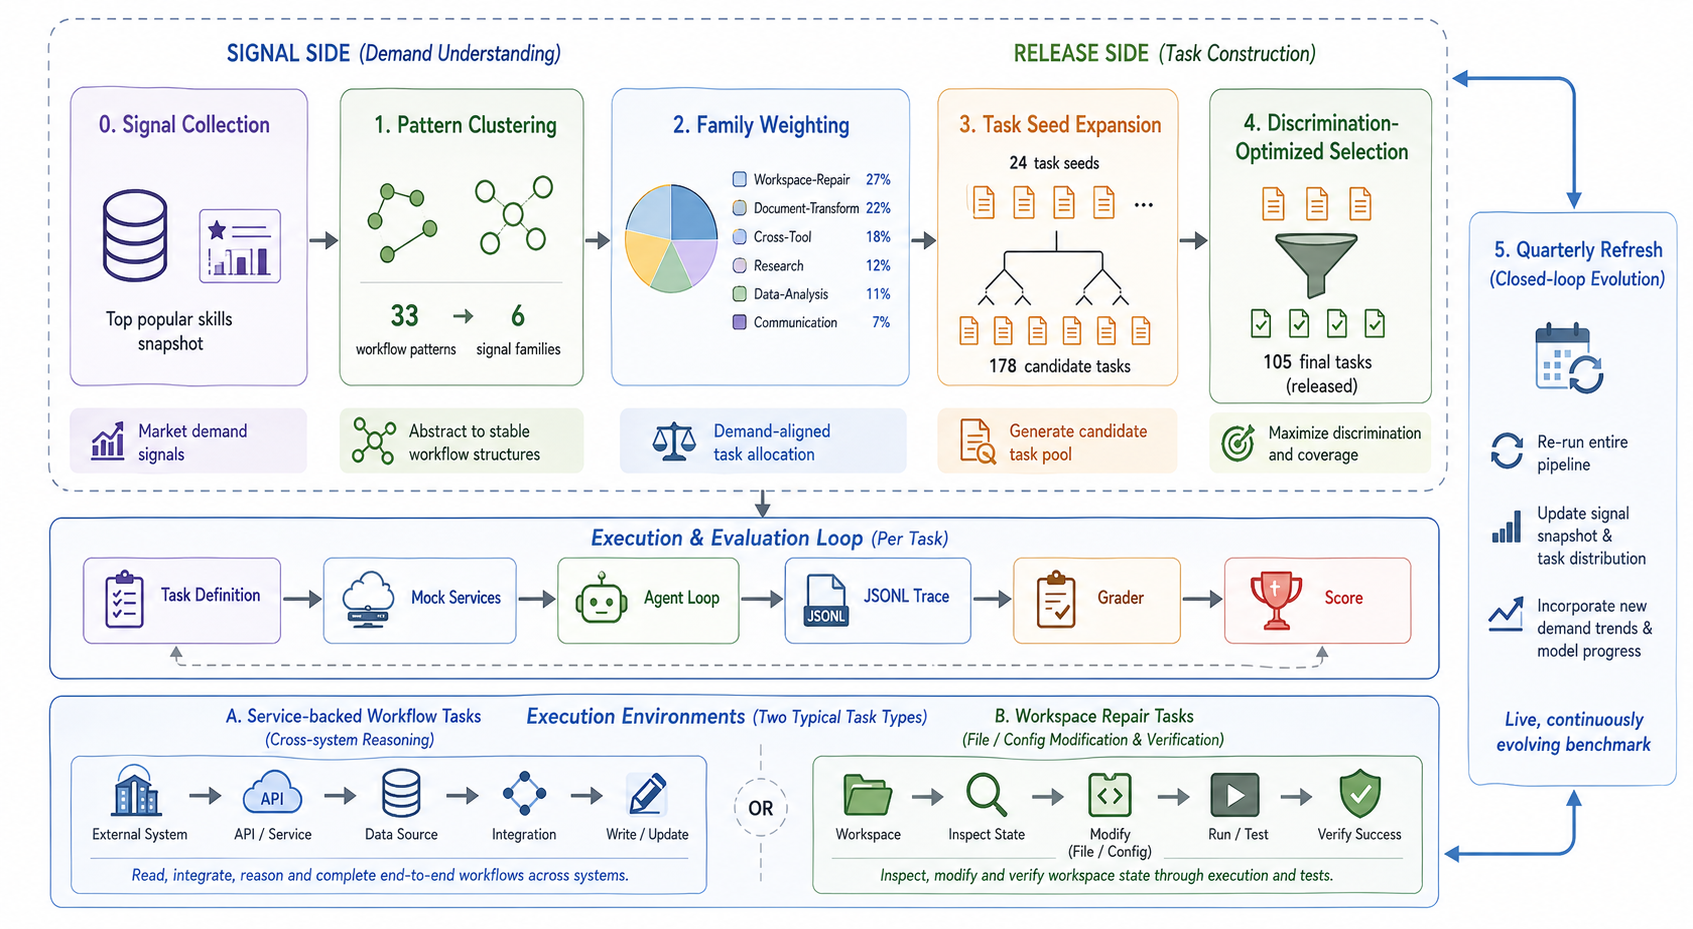
Claw-Eval (Live): A Live Agent Benchmark for Evolving Real-World Workflows
Chenxin Li†, Zhengyang Tang, Huangxin Lin, Yunlong Lin, Shijue Huang, Shengyuan Liu, etc.
arXiv preprint, 2026
Towards On-policy Data Evolution for Visual-Native Multimodal Deep Search Agents
Shijue Huang, Hangyu Guo, Chenxin Li, Junting Lu, Xinyu Geng, Zhaochen Su, etc.
NeurIPS 2026
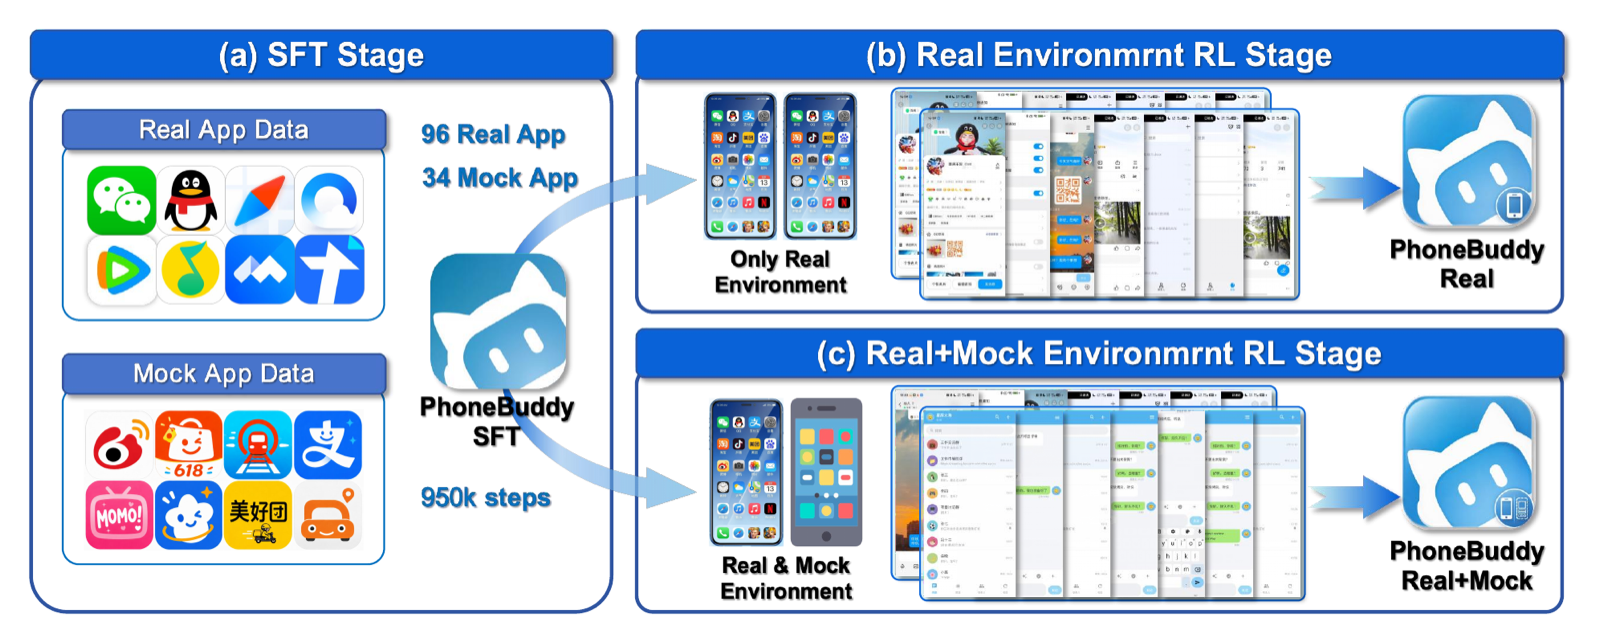
PhoneBuddy: Training Open Models for Agentic Phone Use
Zhengyang Tang, Xin Lai, Pengyuan Lyu, Xinyuan Wang, Tianyi Bai, Chenxin Li, etc.
arXiv preprint, 2026
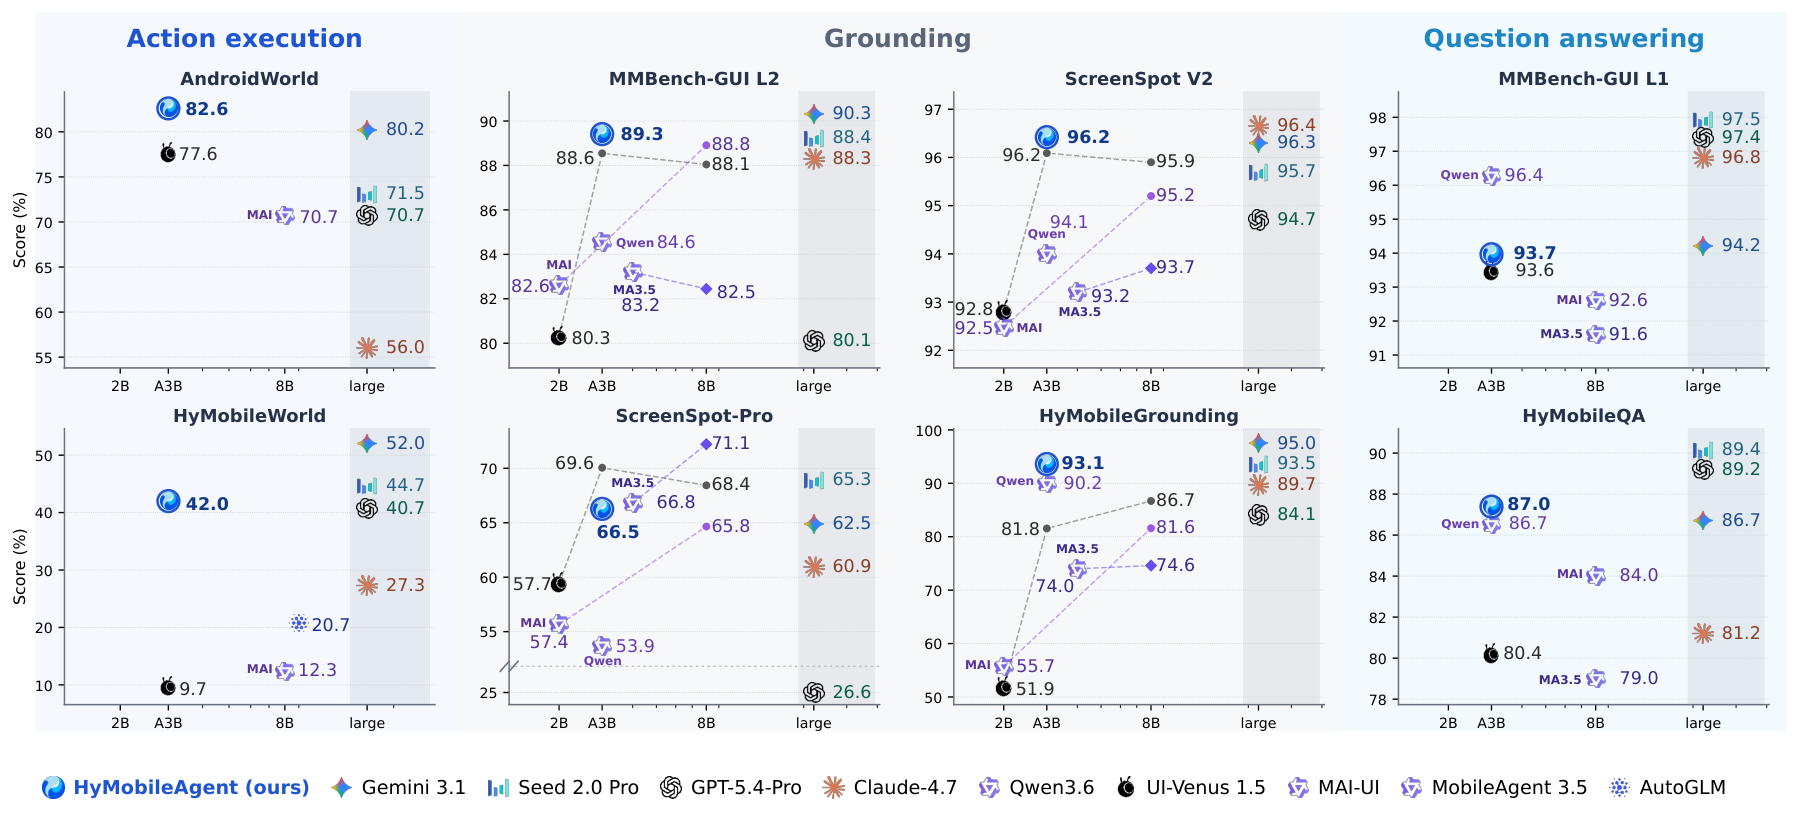
HyMobileAgent: Data-Environment Co-Scaling for Efficient GUI Agents
Tencent HY Team (including Chenxin Li)
arXiv preprint, 2026
GameCraft-Bench: Can Agents Build Playable Games End-to-End in a Real Game Engine?
Tongxu Luo, Rongsheng Wang, Jiaxi Bi, Chenming Xu, Zhengyang Tang, …, Chenxin Li, etc.
arXiv preprint, 2026
PhoneHarness: Harnessing Phone-Use Agents through Mixed GUI, CLI, and Tool Actions
Chenxin Li*, Zhengyao Fang*, Zhengyang Tang*, Pengyuan Lyu*, Xingran Zhou, Xin Lai, etc.
arXiv preprint, 2026
Struct-to-Reason: Enhancing Video Understanding of VLMs via Structured Summary
Hengyu Liu, Chenxin Li*, Wenbo Hu, Zhiqin Yang, Yuxin Chen, Ying Shan, etc.
ICML 2026 Workshop (CompLearn), Poster
SAM-Agent: Empowering Interactive Medical Image Segmentation with Multi-turn Agentic Reinforcement Learning
Shengyuan Liu, Liuxin Bao, Qi Yang, Wanting Geng, Boyun Zheng, Chenxin Li, etc.
ICML 2026
JarvisHub: An Open Harness for Canvas-Native Multimodal Creative Agents
Yunlong Lin, Zixu Lin, Zhaohu Xing, Biqiang Li, Chenxin Li, Haonan Wang, etc.
Technical report, 2026
Thinking in Dynamics: How Multimodal Large Language Models Perceive, Track, and Reason Dynamics in Physical 4D World
Yuzhi Huang, Kairun Wen, Rongxin Gao, Dongxuan Liu, Yibin Lou, Jie Wu, …, Chenxin Li, etc.
NeurIPS 2026
Safe, or Simply Incapable? Rethinking Safety Evaluation for Phone-Use Agents
Zhengyang Tang*, Yi Zhang*, Chenxin Li, Xin Lai, et al.
NeurIPS 2026 (ED Track)
Do Phone-Use Agents Respect Your Privacy?
Zhengyang Tang*, Ke Ji*, Xidong Wang*, Zihan Ye*, Xinyuan Wang, Yiduo Guo, …, Chenxin Li, etc.
arXiv preprint, 2026
PhoneWorld: Scaling Phone-Use Agent Environments
Zhengyang Tang*, Yuxuan Liu*, Xin Lai*, Junyi Li*, Pengyuan Lyu*, Chenxin Li*, et al.
arXiv preprint, 2026
IR3D-Bench: Evaluating Vision-Language Model Scene Understanding as Agentic Inverse Rendering
Parker Liu*, Chenxin Li*, Zhengxin Li, Yipeng Wu, Wuyang Li, Zhiqin Yang, etc.
NeurIPS 2025
JarvisArt: Liberating Human Artistic Creativity via an Intelligent Photo Retouching Agent
Yunlong Lin*, Zixu Lin*, Kunjie Lin*, Chenxin Li*, Haoyu Chen, Zhongdao Wang, etc.
NeurIPS 2025
JarvisIR: Elevating Autonomous Driving Perception with Intelligent Image Restoration
Yunlong Lin*, Zixu Lin*, Haoyu Chen*, Chenxin Li*, Sixiang Chen, Kairun Wen, etc.
CVPR 2025
MonoSplat: Generalizable 3D Gaussian Splatting from Monocular Depth Foundation Models
Yifan Liu, Keyu Fan, Weihao Yu, Chenxin Li, Hao Lu, Yixuan Yuan
CVPR 2025
DynamicVerse: A Physically-Aware Multimodal Framework for 4D World Modeling
Kairun Wen, Yuzhi Huang, Runyu Chen, Hui Zheng, Yunlong Lin, Panwang Pan, Chenxin Li, etc.
arXiv preprint, 2025
FlexGS: Train Once, Deploy Everywhere with Many-in-One Flexible 3D Gaussian Splatting
Hengyu Liu*, Yuehao Wang*, Chenxin Li*, Ruisi Cai, Kevin Wang, Wuyang Li, etc.
CVPR 2025
U-KAN Makes Strong Backbone for Medical Image Segmentation and Generation
Chenxin Li*, Xinyu Liu*, Wuyang Li*, Cheng Wang*, Hengyu Liu, Yifan Liu, etc.
AAAI 2025, Awarded AAAI 2025 Most Influential Paper by PaperDigest (2025).
Talks
  • Invited Talk at the NICE community. RobotWorld: Benchmarking Multimodal Agents for Robot Use Across Diverse Tasks and Embodiments. Oct 2026. [Post]
  • Invited Talk at Shenzhen Research Institute, Tsinghua University. RobotWorld: Benchmarking Multimodal Agents for Robot Use Across Diverse Tasks and Embodiments. Oct 2026. [Post]
  • Invited Talk at VALSE Summit. U-KAN Makes Strong Backbone for Visual Understanding and Generation. Jun 2025.
  • Invited Talk at DAMTP, University of Cambridge. U-KAN Makes Strong Backbone for Visual Understanding and Generation. Jul 2025.
Service
Awards / Honors
  • Tencent TEG 2026 H1 SEVP Award (core contributor to Agent project),2026
  • NSFC Young Student Basic Research Program (Hong Kong and Macao), 国自然博士基金,2026.
  • AAAI 2025 Most Influential Paper, selected by PaperDigest (2025).
  • National Scholarship ×2 (2021, 2022).